Key Takeaways
Building an effective Python scraper for MercadoLibre
💡 Key Takeaways for Scraping MercadoLibre
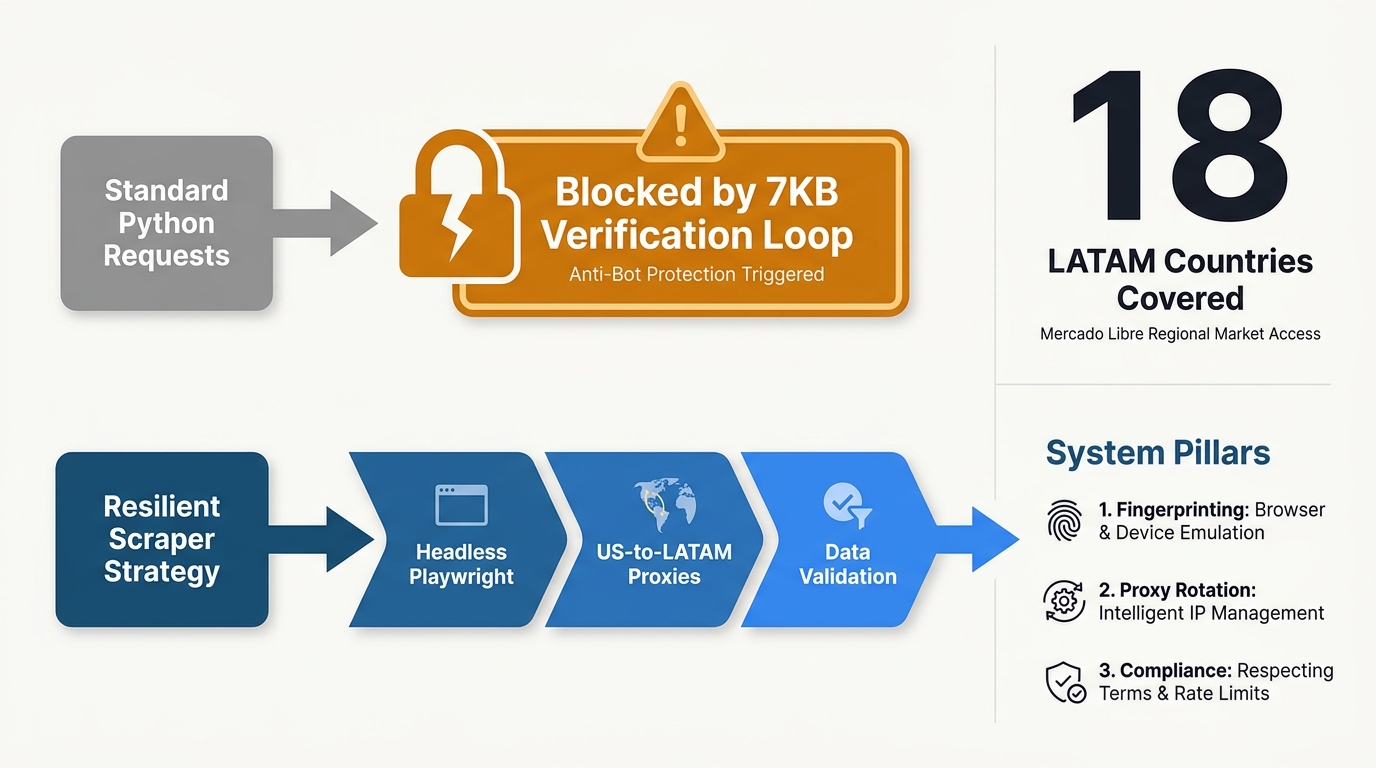
Successfully scraping MercadoLibre requires a multi-faceted approach. You must bypass bot detection with a fingerprinted headless browser, scale your requests using residential proxies, and ensure data quality through validation and legal compliance.
requires bypassing advanced anti-bot measures like Cloudflare’s 7KB verification loop. Standard scripts using requests will fail. Success hinges on a three-part strategy: using a headless browser like Playwright with proper fingerprinting, rotating US-based residential proxies to access LATAM data without blocks, and implementing defensive data validation to ensure accuracy.
Introduction: The Value and Challenge of MercadoLibre Data
For US-based companies, MercadoLibre is a treasure trove of market intelligence. As the dominant e-commerce platform across 18 Latin American countries, its public data fuels critical business strategies, from competitive price monitoring and supply chain analysis to identifying cross-border arbitrage opportunities. According to Actowiz Solutions, extracting this data is essential for building a comprehensive multi-country pricing strategy in the rapidly growing LATAM market.
However, most developers quickly discover that scraping MercadoLibre is notoriously difficult. A simple Python script often gets blocked before fetching a single product page. This is not an accident; the platform employs sophisticated anti-bot systems designed to stop automated traffic.
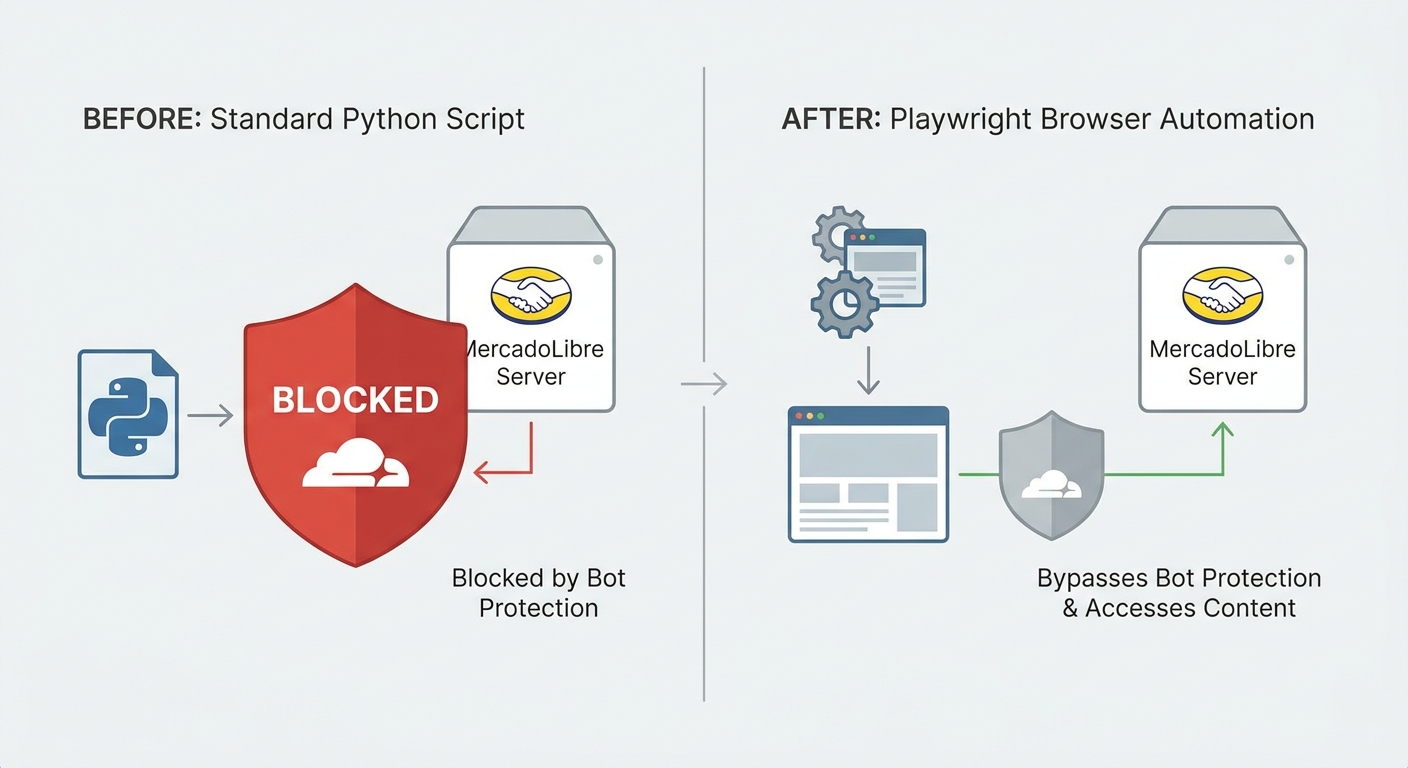
This guide provides a technical blueprint for building a resilient Python scraper that overcomes these defenses. We will detail the specific mechanisms behind MercadoLibre’s blocks and provide a production-ready, three-pillar solution for successfully extracting data at scale.
Author Credentials & Transparency
- Author: ProxyServer.tech Engineering Team
- Bio: We are enterprise infrastructure providers specializing in high-success-rate residential and mobile proxies for large-scale, ethical web scraping and data extraction.
- Transparency Disclosure: This guide contains technical methodologies for web scraping. ProxyServer.tech provides the proxy infrastructure mentioned in the scaling sections. We advocate for the ethical scraping of public data in full compliance with data privacy regulations like GDPR and CCPA.
Pillar 1: Bypassing Bot Detection with a Headless Browser
The primary reason a standard Python requests script fails is that MercadoLibre detects it is not a real browser. As one developer on Reddit noted, “You can start with requests and bs4, but you’ll run out of steam fast due to anti-scraping measures.”
When the platform’s anti-bot system, often Cloudflare, detects a non-browser request, it doesn’t return the product data. Instead, it serves a 7KB JavaScript challenge page. This “verification loop” is designed to be solved only by a browser capable of executing JavaScript, effectively halting simple scrapers. The developer community consensus is clear: “The root problem: MercadoLibre detects and blocks requests (pure Python) because the request doesn’t have a real browser fingerprint.”
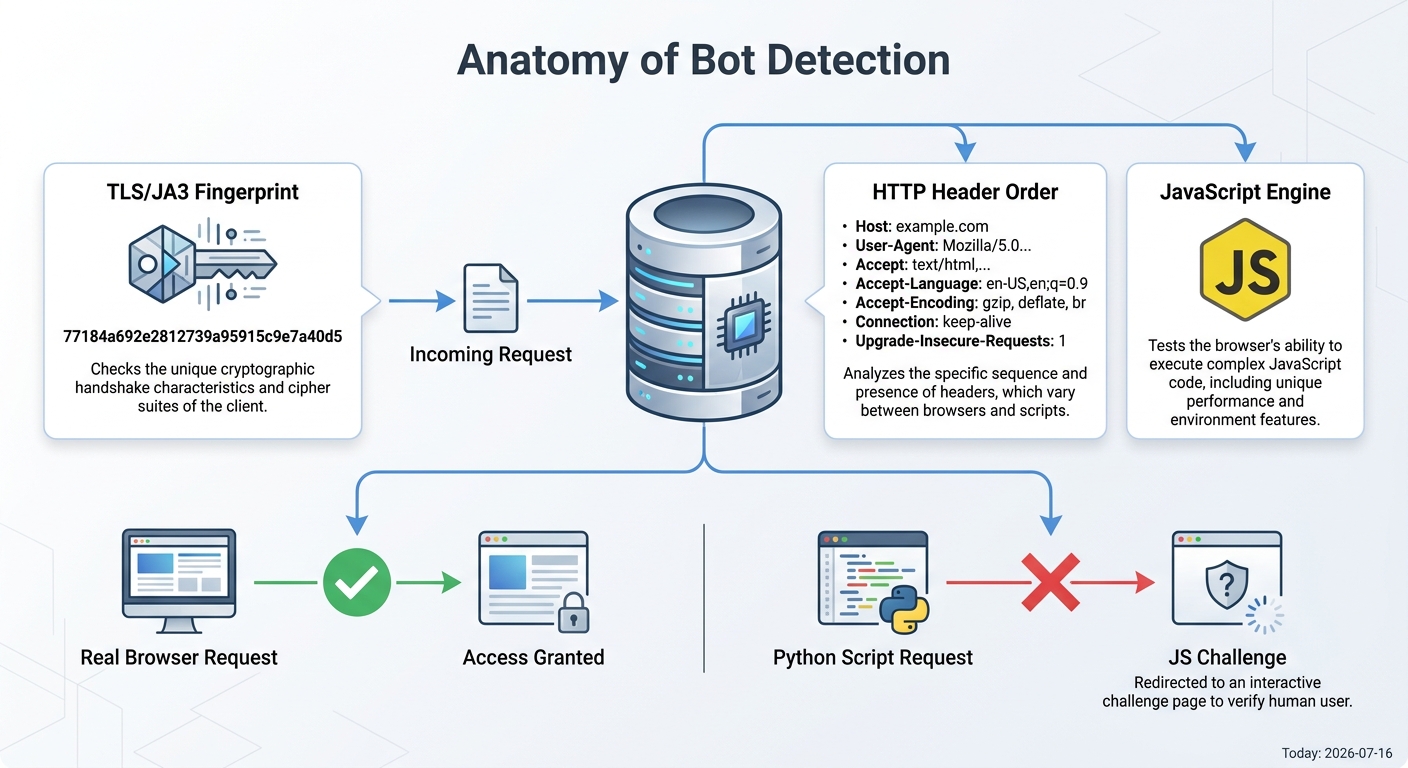
These systems analyze far more than just the User-Agent header. They inspect the request’s entire signature, including:
- TLS/JA3 Fingerprint: The specific combination of ciphers and protocols used to initiate a secure connection, which differs between a Python script and a real browser.
- HTTP Headers: The order and presence of headers.
- JavaScript Engine: The ability to render and interact with a dynamic page.
The solution is to use a headless browser automation framework like Playwright
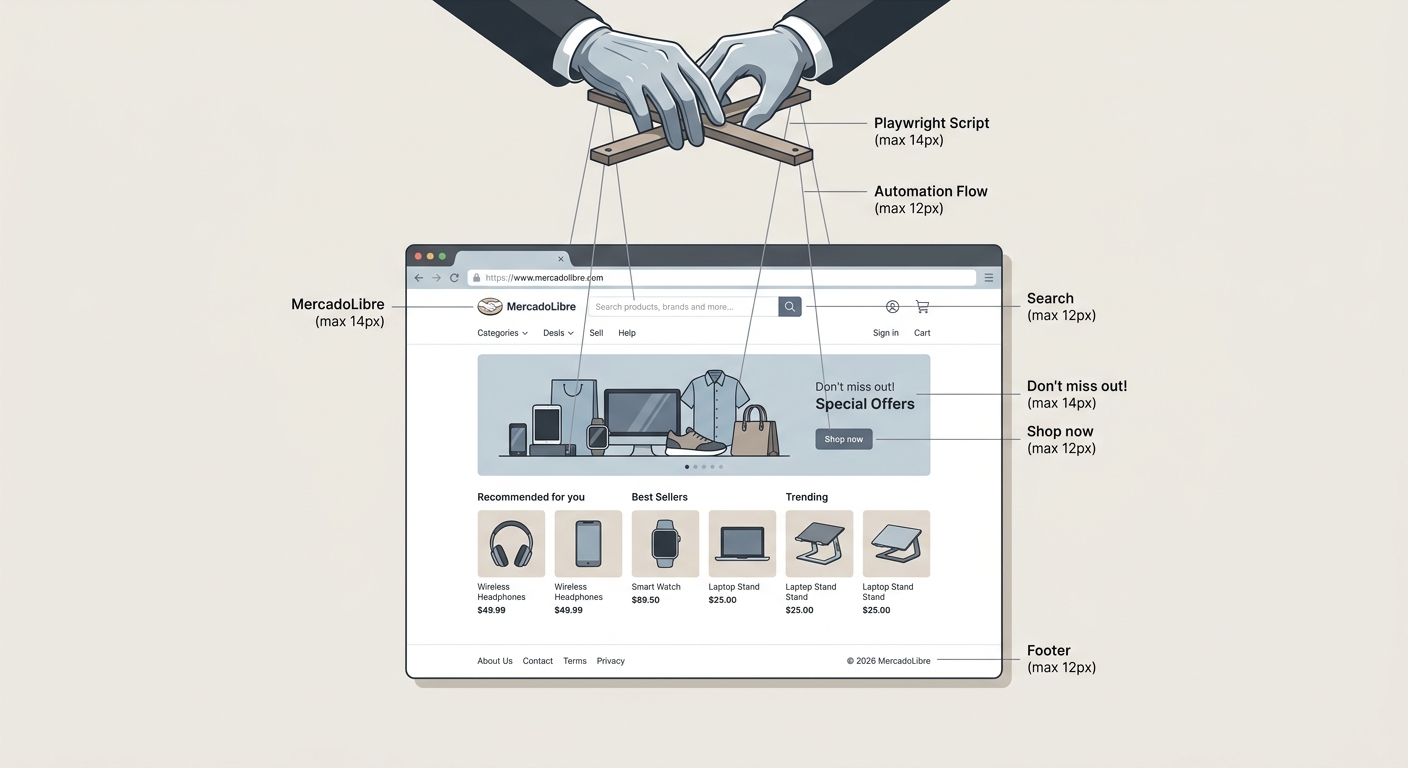
or Selenium. These tools control a real browser engine (like Chromium) programmatically. However, even headless browsers can be detected. You must actively mask their automated nature by “fingerprinting” them to appear human. This involves launching the browser and using scripts to remove automation tells (like the navigator.webdriver
✅ Pro Tip: Browser Fingerprinting
Even headless browsers can be detected. To appear fully human, your script must modify the browser environment to remove automation flags (like `navigator.webdriver`) and mimic the properties of a standard Chrome or Firefox installation.
property) and inject properties a normal browser would have (like window.chrome). This allows the headless browser to solve the JavaScript challenge and access the real page content.
Pillar 2: Scaling with Residential Proxy Rotation
Successfully bypassing bot detection on a single request is just the first step. To scrape at scale from a US-based server, you must address network-level challenges like rate limiting and geo-blocking. Making thousands of requests from a single IP address is a clear signal of automation and will result in a swift block.
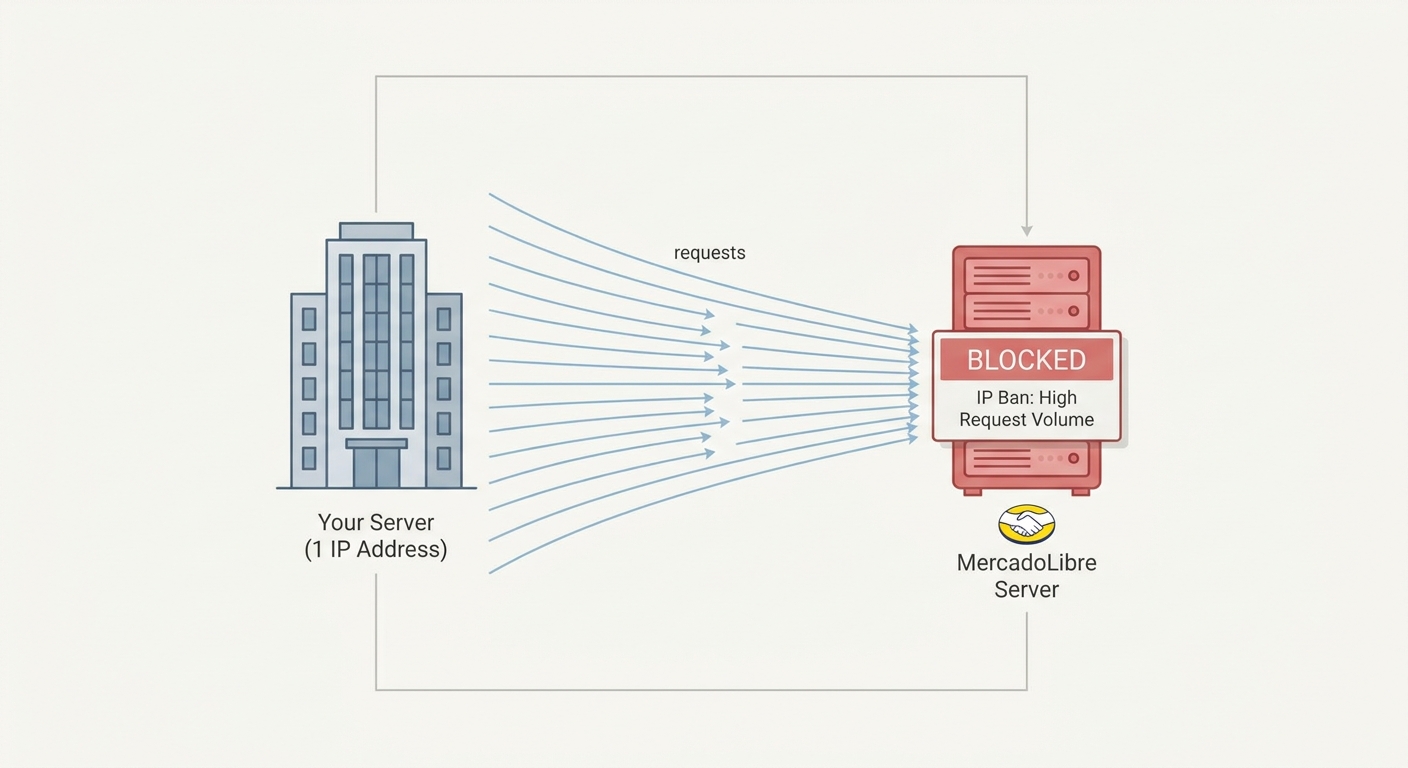
The solution is proxy rotation
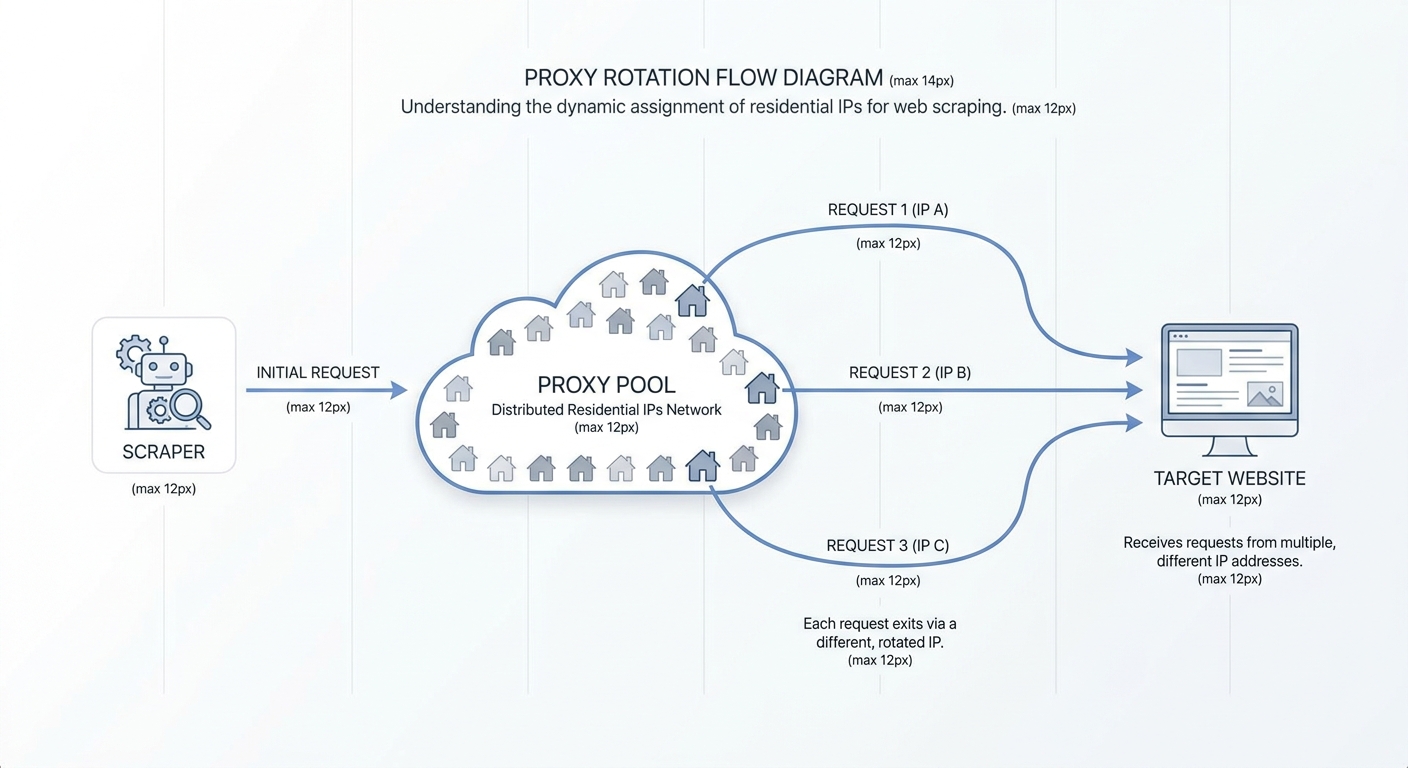
. By routing your requests through a pool of proxies, you automatically swap your outbound IP address, making your scraper appear as thousands of unique, organic users. This prevents any single IP from accumulating enough requests to trigger a block.
For scraping a LATAM-focused site like MercadoLibre, residential proxies are the industry standard. These are IP addresses assigned by Internet Service Providers (ISPs) to real home devices. They carry a much higher trust signal than datacenter IPs (which are easily identified and blocked) and are essential for accessing country-specific pricing and product availability (e.g., on mercadolibre.com.mx
Proxy Types for Web Scraping
| Option | Pros | Cons | Score |
|---|---|---|---|
| Datacenter Proxies | Fast and inexpensive. | Easily detected and blocked by sophisticated sites like MercadoLibre. Low trust signal. |
4/10
|
| Residential Proxies | Real IP addresses from ISPs. High trust signal, making them effective at bypassing blocks and geo-restrictions. | More expensive than datacenter proxies. |
9/10
|
vs. mercadolibre.com.ar).
The following Python snippet demonstrates how to integrate a rotating residential proxy endpoint with Playwright:
📦 Import Playwright
Start by importing the necessary `sync_playwright` function.
🔑 Define Proxy Credentials
Set up your proxy server endpoint, port, username, and password.
🚀 Launch Browser with Proxy
Instantiate a Chromium browser, passing the proxy details in the `launch` configuration.
🕸️ Navigate and Scrape
Use the created `page` object to navigate to your target URL. All requests will now be routed through the proxy.
from playwright.sync_api import sync_playwright

# Your rotating residential proxy endpoint and credentials
PROXY_SERVER = "us.residential.proxyserver.tech"
PROXY_PORT = 8000
PROXY_USER = "your_username"
PROXY_PASS = "your_password_from_dashboard"

with sync_playwright() as p:
    # Launch a Chromium browser instance configured to use the proxy
    browser = p.chromium.launch(
        headless=True,  # Run in the background without a visible UI
        proxy={
            "server": f"http://{PROXY_SERVER}:{PROXY_PORT}",
            "username": PROXY_USER,
            "password": PROXY_PASS
        }
    )
    page = browser.new_page()

    try:
        # Each request made through this page will use a new IP from the proxy pool
        page.goto("https://www.mercadolibre.com.mx/p/MLM28037193", timeout=60000)

        # --- Your data extraction logic here ---
        # Example: Extract the product title
        title = page.locator('h1.ui-pdp-title').inner_text()
        print(f"Product Title: {title}")

    except Exception as e:
        print(f"An error occurred: {e}")
    finally:
        browser.close()
A production-grade system requires more than just swapping IPs. You must distribute requests evenly across the proxy pool to improve speed and stability [9]. This also involves implementing robust retry logic. For example, a common configuration is to retry a failed URL up to two times, using residential proxies from a specific region like the US to standardize the origin point of your requests [7]. Premium residential proxies can achieve success rates above 99.8%, a critical metric for large-scale operations.
📊 Success Rate is Key
For large-scale data operations, the success rate of your requests is a critical metric. Premium residential proxies can achieve over 99.8% success, minimizing data loss and the need for complex retry logic.
Pillar 3: Ensuring Data Integrity and Legal Compliance
A scraper is only useful if its data is accurate and its operations are legally sound. This requires building defensive systems for data validation and a firm understanding of the legal landscape.
Defensive Data Validation: Website layouts change. A simple CSS class name update for a product’s price can cause a naive scraper to fail silently or, worse, log thousands of items with a price of $0.00. To prevent this data corruption, you must implement rigid schema validation. Frameworks like Scrapy use an “Item Pipeline” to process and validate every piece of data against a predefined schema before it’s saved to your database [4]
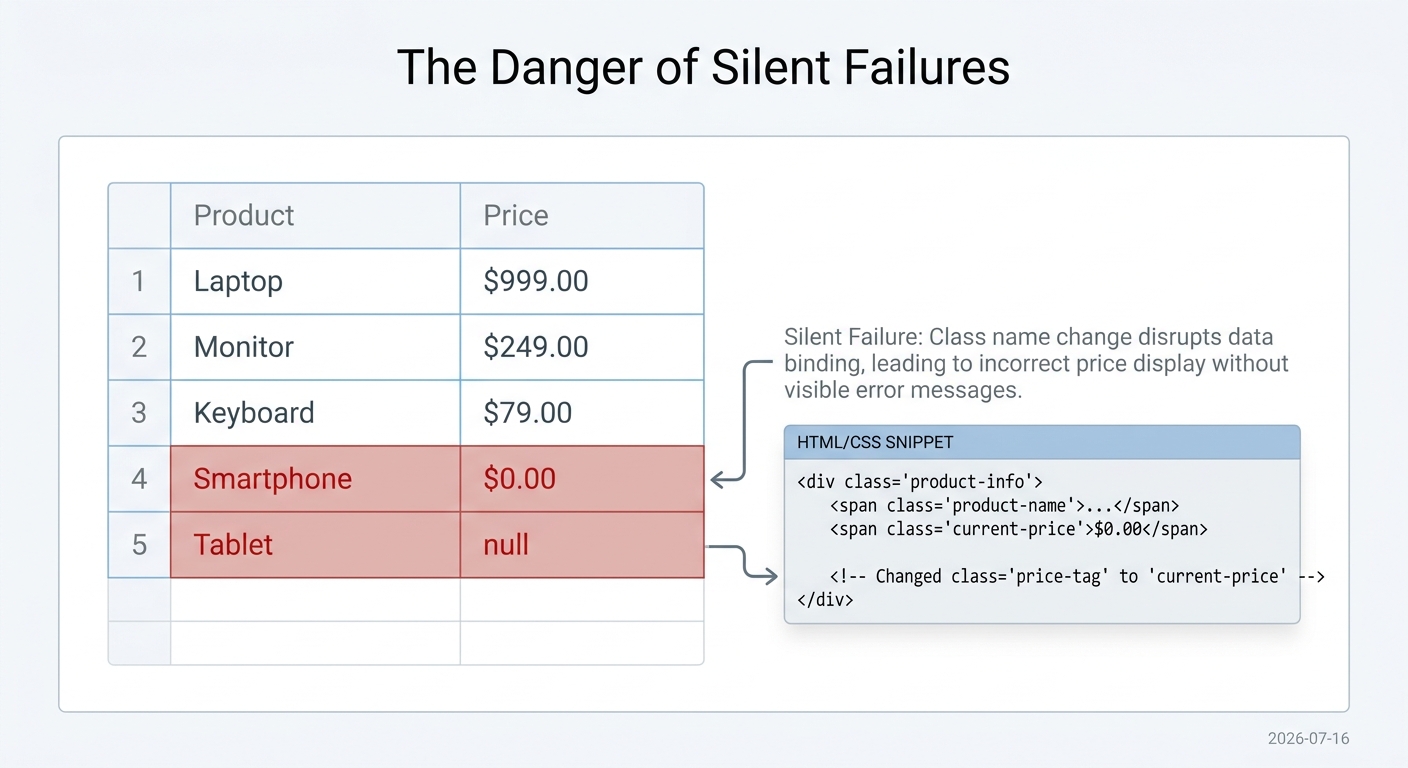
. This ensures data integrity even when the source HTML is unexpectedly modified [6].
Legal Compliance: Web scraping public data is not inherently illegal, but the legal environment has become increasingly complex [3]
⚠️ Legal & Ethical Compliance
While scraping public data is generally permissible, you must operate within legal frameworks. Avoid scraping personal data to comply with GDPR/CCPA, do not scrape copyrighted content like images, and always respect the website’s `robots.txt` file as a guideline for ethical conduct.
. When operating from the US and scraping data from other regions, you must be mindful of data privacy laws like Europe’s GDPR and California’s CCPA [2]. These regulations impose strict requirements on collecting and processing personal data.
It is critical to distinguish between public business data (product prices, stock levels, specifications) and protected or personal data [1]. To remain compliant, your scraping activities should focus exclusively on the former. Avoid scraping copyrighted content (like product descriptions and images) or user-generated content (like reviews containing personal information). For more guidance on ethical data handling, review our anti-fraud policy.
FAQ: Scraping MercadoLibre
How do I bypass MercadoLibre’s 7KB verification page?
Use a headless browser like Playwright with proper fingerprinting. The 7KB page is a JavaScript challenge from Cloudflare that a standard Python requests call cannot execute. A headless browser can, but you must mask automation tells, like the navigator.webdriver flag, to appear as a real user.
What are the best proxies for scraping LATAM e-commerce from the US?
Rotating residential proxies are the best choice. They provide real IP addresses from local ISPs, helping you bypass geo-blocks and IP-based rate limits. They carry a much higher trust signal than datacenter proxies, which are frequently blacklisted by sites like MercadoLibre.
Why is MercadoLibre blocking my Python requests?
MercadoLibre uses advanced anti-bot protection that analyzes your entire request signature, not just your User-Agent. It detects automated scripts by checking for inconsistencies in TLS/JA3 fingerprints, HTTP header order, and the absence of a JavaScript execution environment. A basic Python script fails these checks and is blocked.
Is it legal to scrape public product data from MercadoLibre?
Scraping publicly available data like prices and stock status is generally permissible, but compliance is key. You must adhere to data privacy regulations like GDPR and CCPA. Avoid scraping copyrighted content (images, descriptions) and personal data (user reviews). Always respect robots.txt as a baseline for ethical conduct [5].
Conclusion: A Three-Pillar Approach to Success
Successfully scraping MercadoLibre is not about finding a single magic script; it’s about implementing a resilient, multi-layered architecture. By building your system on three core pillars, you can overcome the platform’s advanced defenses and unlock valuable market data.
- Headless Browsers: Use Playwright to defeat JavaScript challenges and mimic human behavior.
- Residential Proxies: Implement proxy rotation to avoid IP blocks and access geo-specific data at scale.
- Defensive Design: Integrate schema validation and adhere to legal best practices to ensure data quality and compliance.
This strategic approach transforms the challenge of scraping MercadoLibre from an obstacle into a scalable, reliable data pipeline. To build the high-performance infrastructure your project demands, explore ProxyServer.tech’s residential proxy solutions.
References
[1] E-Commerce Scraper Legal Guide: ToS, GDPR & Compliance | ShoppingScraper | ShoppingScraper
[3] Is Web Scraping Legal? Understanding Web Scraping Compliance
[4] Scrapy: Everything you need to know about this Python web scraping tool
[5] Python Web Scraping Guide: Tools, Code & Best Practices
[6] What are the web scraping best practices that actually matter in a
[7] Mercado Libre Product Search Scraper · Apify
[8] Web Scraping in Python With BeautifulSoup: Tutorial to Production